Backup and Redundancy
GCP Managed Services — Backup/Restore & Redundancy (ISO Audit Evidence)
Scope: CM Marketplace production environment — Cloud SQL, Memorystore (Redis), GKE, Pub/Sub, Cloud Run. All five are fully GCP-managed services; redundancy and backup mechanisms are provided by the platform under GCP's SLA rather than self-managed tooling.
1. Cloud SQL
Redundancy: availability_type = REGIONAL — GCP maintains a synchronous standby replica in a second zone within europe-west4 (primary zone europe-west4-c). On zone failure, GCP automatically fails over to the standby with no manual intervention; this is Google's built-in HA mechanism for Cloud SQL, not custom infrastructure.
Backup mechanism (GCP-native):
- Automated daily backups, enabled via
backup_configuration(start time 12:00), retaining 7 backups (count-based retention). - Point-in-time recovery (PITR) enabled, with 7 days of transaction log retention — allows restore to any second within that window, not just backup snapshots.
- Backups stored in the
eumulti-region for geographic durability independent of the primary instance's zone/region. deletion_protectionandprevent_destroylifecycle guard against accidental instance deletion.
Restore test performed:
- Date of test:
July 13, 2026 - Backup/PITR timestamp restored from:
July 12, 2026 7:09 PM - Restore target:
Replaced existing instance - Validation performed (row counts, checksum, application smoke test, etc.):
Verified environment is working - Observed RTO / RPO:
15 mins
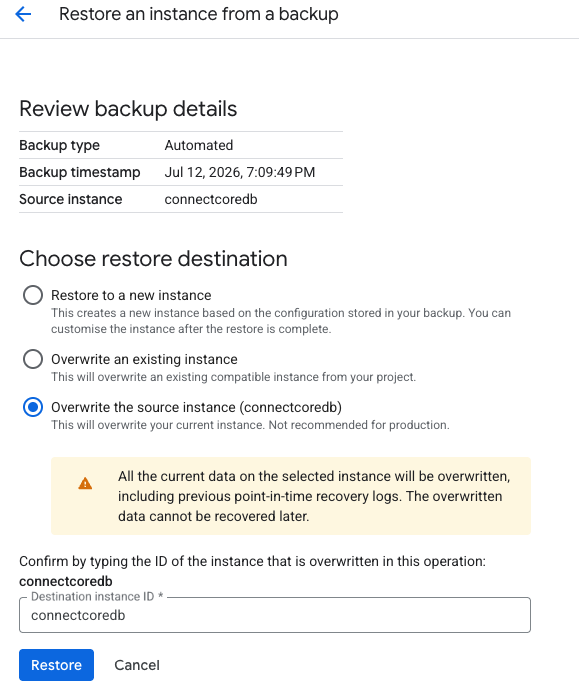
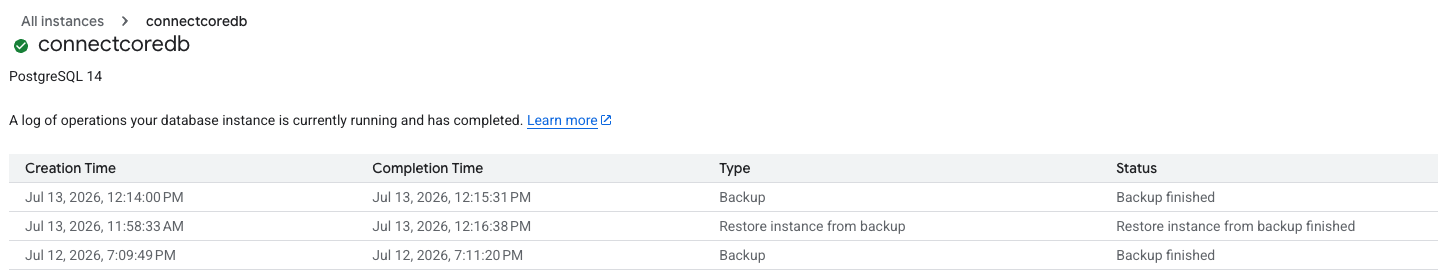
Cloud SQL's managed backup/restore service means CM does not maintain custom backup scripts or storage — GCP guarantees backup execution, encryption at rest, and restore capability as part of the Cloud SQL product, and this test demonstrates that capability works as documented.
2. Memorystore for Redis
Current config: tier = BASIC, replica_count = 0, read_replicas_mode = DISABLED, persistence_config.persistence_mode = DISABLED.
Note for the audit: BASIC tier is a single-node instance with no automatic failover and no data persistence — a zone or node failure causes data loss and requires GCP to recreate the instance (cache is treated as ephemeral by design). This is expected for a cache layer, but it means Redis does not currently meet the same redundancy bar as Cloud SQL/GKE. If the audit expects redundancy guarantees across all managed services, flag this explicitly rather than imply HA — the remediation would be moving to STANDARD_HA tier (adds a cross-zone replica with automatic failover) and enabling RDB persistence if the cached data ever needs to survive a restart.
3. GKE
Redundancy: Regional Autopilot cluster (location = europe-west4, a region, not a single zone). Google manages the control plane across multiple zones with automatic failover, and Autopilot handles node provisioning/rescheduling across zones transparently — no customer-managed node pools or manual HA configuration required. This redundancy is covered under the GKE Autopilot regional SLA.
4. Pub/Sub
Redundancy: Google replicates published messages synchronously across multiple zones internally as part of the Pub/Sub service — this is inherent to the product and requires no configuration.
Resilience configuration in this repo: every subscription (TokenRefresh, CRMEventsToCDP, CRMEvents, etc.) is configured with a dead-letter topic (Events-error, max 5 delivery attempts) and an exponential retry policy (10s–600s backoff), ensuring message processing failures don't result in data loss even if a downstream Cloud Run service is temporarily unavailable.
5. Cloud Run
Redundancy: Fully managed, regional service — Google distributes running instances across multiple zones within the region automatically. minScale (1–2 depending on service) keeps warm instances available, reducing cold-start-related availability gaps. No customer-managed infrastructure or failover logic exists or is needed.
Summary table
| Service | Redundancy mechanism | Backup/Restore mechanism | Gap / note |
|---|---|---|---|
Cloud SQL (connectcoredb) | Regional HA (auto failover, 2nd zone) | Daily automated backups (7 retained) + PITR (7-day log retention) | None — tested |
Redis (connectcache) | None (BASIC tier, single node) | None (persistence disabled) | Flag: no HA, no persistence. (We can load into cache from DB on cache miss) |
| GKE (Autopilot) | Regional control plane + auto node rescheduling across zones | N/A (stateless workloads; state lives in Cloud SQL/Redis) | — |
| Pub/Sub | Multi-zone message replication (Google-managed) | Dead-letter topics + retry backoff configured on all subscriptions | — |
| Cloud Run | Multi-zone instance distribution (Google-managed) | N/A (stateless) | — |